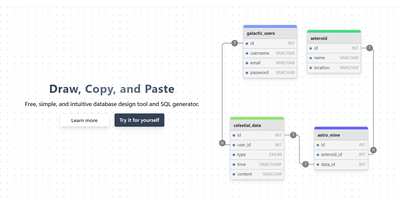
drawDB
Schema design with no account and a few clicks: drawDB is the browser-based entity-relationship diagram editor and SQL generator - an AGPL-3.0 React project with over 37,000 GitHub stars. Draw tables with columns, data types, defaults, and constraints; connect fields to create foreign-key relationships; group tables into labeled subject areas; and annotate with notes. When the design is ready, one export produces CREATE TABLE DDL - with constraints, indexes, and foreign keys - targeted at MySQL, PostgreSQL, SQLite, MariaDB, SQL Server, or Oracle. Diagrams can be database-specific, unlocking every native type plus dialect features like PostgreSQL enums and composite custom types, or generic for portability across all supported flavors. The reverse direction works too: paste existing DDL into the import dialog and drawDB renders your live schema as a navigable diagram - the fastest way to document an inherited database. Versioning and migration-script generation track schema evolution, full editor ergonomics (undo/redo, copy/paste, duplicate, themes) keep iteration fast, and diagrams export as PNG, SVG, or shareable JSON. Everything runs client-side against browser storage - no backend database connection needed - so the self-hosted Docker deployment is a featherweight static app that keeps proprietary schema designs entirely on your infrastructure.
MongoDB
Used by over 46,800 companies including Forbes, Toyota, and Cisco, MongoDB stores data as flexible JSON-like BSON documents that eliminate rigid table schemas and support rapid application iteration. Its aggregation pipeline processes complex data transformations through composable stages including $match, $group, $lookup for joins, $unwind, and $project, operating directly within the database engine. Horizontal scaling is built in through automatic sharding, which distributes data across nodes using range-based, hashed, or zone-based shard keys, while replica sets provide automatic failover with configurable read preferences and write concerns. Multi-document ACID transactions span multiple collections and shards since version 4.0, enabling relational-style consistency guarantees within a document model. Starting with Community Edition 8.2, native full-text search and vector search are available directly in the database through $search and $vectorSearch aggregation stages, supporting RAG patterns, semantic retrieval, and hybrid search without external dependencies. Change streams provide real-time event-driven data access by tailing the oplog through the aggregation framework, enabling reactive architectures without polling. Time series collections offer optimized columnar storage for IoT sensor data and metrics with automatic bucketing and compression. Official drivers exist for Python, Node.js, Java, Go, C#, C++, Rust, Swift, and PHP, with MongoDB Compass providing a GUI for visual schema exploration and query building. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. SSPL v1 licensed.
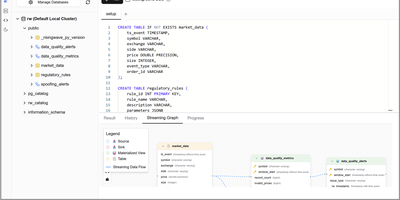
RisingWave
With over 9,100 GitHub stars and production deployments powering real-time analytics at companies like SHOPLINE where it reduced API latency by 76.7%, RisingWave is the PostgreSQL-compatible streaming database that collapses the traditional Debezium-plus-Kafka-plus-Flink-plus-serving-database stack into a single Rust-powered system. The platform continuously ingests data from PostgreSQL and MySQL via native CDC connectors that eliminate Debezium middleware, consumes Kafka, Redpanda, Pulsar, and Kinesis topics, accepts webhook events from SaaS applications, and batch-loads historical data from S3 and data warehouses. Standard SQL defines sources, materialized views, and sinks — no new DSL, no Java, and no custom API — while the PostgreSQL wire protocol means psql, DBeaver, pgAdmin, Grafana, Metabase, Superset, Tableau, and every PostgreSQL client library works without modification. Materialized views are incrementally maintained as events arrive, delivering point lookups in single-digit milliseconds without recomputing aggregates from scratch. For long-term retention, RisingWave writes to Apache Iceberg tables with a hosted REST catalog and automated table maintenance including compaction, small-file optimization, and snapshot cleanup, with data queryable by Spark, Trino, DuckDB, and DataFusion. The disaggregated compute-storage architecture uses S3-based state management for elastic scaling, instant failure recovery measured in seconds rather than the minutes-to-hours typical of RocksDB-based systems, and cost-efficient storage tiering. An MCP server enables AI agents to query and operate RisingWave directly. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
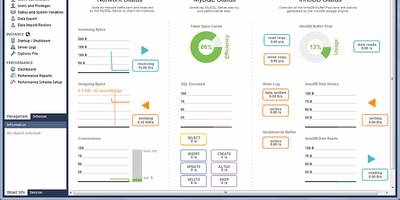
MySQL
Powering Facebook, Uber, Twitter, and Booking.com, MySQL processes billions of queries daily as the world's most widely deployed open-source relational database. Its default InnoDB storage engine delivers full ACID compliance with row-level locking, crash recovery, and foreign key enforcement, making it the backbone of mission-critical e-commerce, SaaS, and financial applications. MySQL's Document Store bridges relational and NoSQL paradigms, allowing developers to work with schema-less JSON collections alongside traditional SQL tables through the X DevAPI protocol. For high availability, InnoDB Cluster combines Group Replication, MySQL Router, and MySQL Shell into an integrated solution with automatic failover, while InnoDB ClusterSet extends this across data centers for disaster recovery. The database supports multiple storage engines including MyISAM for read-heavy analytics, Memory for temporary high-speed caching, and Archive for compressed historical data. Native JSON functions like JSON_TABLE() transform document data into relational result sets, and spatial data types enable GIS applications. MySQL integrates with every major programming language through official connectors for Python, Java, Node.js, PHP, C++, and .NET, and works seamlessly with frameworks like Django, Laravel, Rails, and Spring. Replication topologies support read replicas for horizontal scaling, and the new Change Stream Applier in MySQL 26.7 enables configurable parallel transaction application with up to 1,024 workers per channel. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. GPLv2 licensed.
Portabase
Portabase takes a zero-trust approach to database backups: lightweight Rust/Tokio agents deploy next to each database, encrypt dumps with AES-GCM before data ever leaves the host, and poll the Next.js control plane outbound every five seconds requiring zero inbound firewall rules. This architecture contains blast radius if the dashboard is compromised while supporting ten engines with stable backup and restore: PostgreSQL 12 through 18, MySQL 5.7 through 9, MariaDB 10 and 11, MongoDB 4 through 8, SQLite 3.x, Redis 2.8+, Valkey 7.2+, Firebird 3.0 through 5.0, Microsoft SQL Server 2017 through 2022 including Azure SQL, and Docker volumes on Engine 20.10+. Encrypted backups store on configurable backends including local filesystems, any S3-compatible provider (AWS, MinIO, RustFS), Google Cloud Storage, and Azure Blob Storage. Cron-based scheduling with Grandfather-Father-Son retention policies automates backup lifecycle management, while on-demand restore targets any compatible server for cross-environment recovery. The CLI installs agents with a single command and auto-updates when new versions ship. A RESTful API with MCP server integration enables automation from CI/CD pipelines and AI agent workflows. Developed by a non-profit under Apache-2.0. 1,270+ stars and 174 releases since October 2024. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console.
FalkorDB
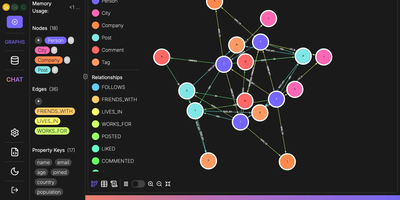
FalkorDB is the first queryable property graph database to leverage sparse adjacency matrices and linear algebra for graph traversal, replacing traditional pointer-chasing with GraphBLAS-accelerated computation. Originally the RedisGraph engine, it was relaunched as FalkorDB in 2023 and rewritten from C to Rust in 2026 for improved memory safety and performance. The database supports the OpenCypher query language with proprietary extensions, translating queries into linear algebra expressions that exploit AVX hardware acceleration. Indexing options include full-text search, vector similarity for embedding-based retrieval, and range indexing, while connectivity supports both the RESP protocol for Redis clients and the Bolt protocol for Neo4j-compatible tooling. The GraphRAG SDK enables ingestion of documents in text, PDF, and Markdown formats into knowledge graphs, with schema-guided entity extraction, hybrid retrieval combining vector and graph traversal, relationship expansion, and cited answers for LLM applications. Official client libraries cover Python, Node.js, Java, Rust, Go, PHP, and C#. Multi-tenant support handles over 10,000 concurrent graphs with zero overhead and full isolation. Docker deployment runs the falkordb/falkordb image on ports 6379 for the database server and 3000 for the built-in browser UI, with persistent volume storage and optional authentication. A production falkordb-server image excludes the browser for lighter deployments. On RepoCloud, deploy FalkorDB on a dedicated VPS with root SSH access, persistent storage for your graph data, and complete control over authentication, thread count, and memory configuration, all under the SSPLv1 license.
Percona PMM
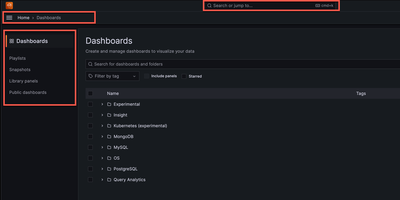
Backed by 1,080+ GitHub stars and maintained by Percona with the latest release v3.8.1 in June 2026, Percona Monitoring and Management delivers the open-source database observability platform that provides a single pane of glass across MySQL, PostgreSQL, MongoDB, Valkey, and Redis databases deployed on-premises, cloud, or hybrid environments. The Go-powered PMM Server collects metrics from lightweight PMM Client agents with minimal performance impact, storing time-series data in ClickHouse for fast querying across configurable retention periods. Query Analytics ranks every query by load across all database engines from one unified dashboard, drilling from fleet-level performance down to individual problematic queries with explain plans, per-query metrics, and anomaly detection. Real-time Query Analytics streams live MongoDB operations updated every 1-5 seconds for immediate troubleshooting of lock contention and long-running queries. Built-in Percona Advisors continuously scan connected databases for security gaps, misconfigurations, and performance problems, distilling decades of DBA expertise into automated actionable recommendations. Percona Alerting integrates with 15+ notification channels including Slack, PagerDuty, email, and webhooks to trigger on custom metric thresholds. Database-specific dashboards visualize InnoDB storage engine details, WiredTiger cache metrics, PostgreSQL tuple activity, replication lag, and cluster health with annotations for root-cause correlation. Deployment options include Docker single-container setup, Podman rootless execution, and Helm charts for Kubernetes with Ingress controller support and ConfigMap management. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
etcd
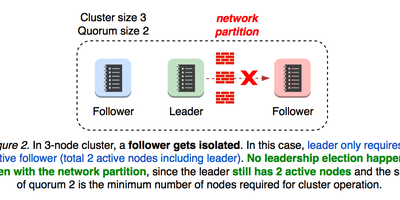
With over 52,000 GitHub stars and its role as the foundation of every Kubernetes cluster worldwide, etcd is the distributed key-value store that handles the most critical data in modern infrastructure — cluster state, configuration, service discovery, and distributed coordination. Built in Go and graduated from the CNCF, etcd uses the Raft consensus algorithm to maintain a strongly-consistent, highly-available replicated log across a cluster of machines, gracefully handling leader elections during network partitions and tolerating machine failure including the leader node. The gRPC API provides atomic key-value operations including put, get, delete, and transactions with multi-key compare-and-swap semantics, enabling distributed locking, leader election, and configuration management without external coordination. Watch operations stream real-time change notifications for specific keys or key ranges, powering reactive architectures that respond immediately to configuration updates. Version 3.7 introduces RangeStream for streaming large result sets in chunks, keys-only range requests for faster metadata queries, and bootstraps entirely from v3store after eliminating the legacy v2 store dependency. Automatic TLS encryption with optional client certificate authentication secures all cluster communication, while role-based access control restricts key access per user. The embedded bbolt B+ tree storage engine provides consistent reads and writes with configurable compaction policies. Benchmarked at 10,000 writes per second per instance with linearizable reads, etcd supports clusters of 3, 5, or 7 members for fault tolerance. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Redis
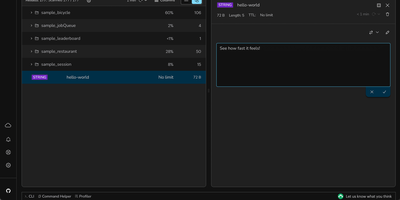
Processing billions of operations per second across companies like Twitter, GitHub, Snapchat, and Stack Overflow, Redis is the world's fastest and most widely deployed in-memory data store. Redis 8 unifies previously separate modules into a single distribution: RediSearch for full-text indexing with BM25 scoring and vector similarity search via HNSW and FLAT algorithms, RedisJSON for native JSON document storage with JSONPath queries, RedisTimeSeries for timestamped data with configurable downsampling compaction rules, and RedisBloom for probabilistic data structures including Bloom filters, cuckoo filters, count-min sketches, top-k, and t-digest. The core engine provides strings, lists, sets, sorted sets, hashes, streams, HyperLogLog, bitmaps, bitfields, geospatial indexes, and the new array data structure introduced in Redis 8.8. Pub/Sub delivers lightweight real-time messaging between publishers and subscribers, while Streams provide an append-only log with consumer groups for event sourcing and complex consumption patterns. Redis Cluster distributes data across nodes with automatic sharding using 16,384 hash slots, and Sentinel provides high availability with automatic failover monitoring. Lua scripting and Redis Functions enable server-side computation, and ACL-based security provides granular per-command, per-key access control. Official clients exist for Python, Node.js, Java, Go, .NET, Rust, and PHP. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPLv3 licensed.
Chroma
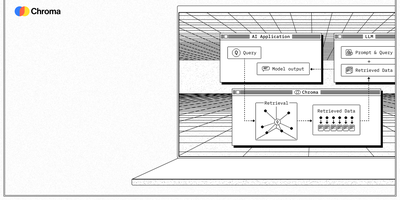
With over 29,000 GitHub stars and deep integrations into LangChain, LlamaIndex, and CrewAI, Chroma has become the default vector database for developers building retrieval-augmented generation pipelines and AI agent memory systems. Its core API consists of just four functions — create, add, query, and delete — making it the fastest path from zero to semantic search, while the underlying Rust engine handles tokenization, embedding, HNSW indexing, and similarity scoring automatically. Chroma supports dense vector search via HNSW with configurable distance metrics including L2, cosine similarity, and inner product, sparse vector search using SPLADE, full-text BM25 keyword search, and regex matching, all combinable in hybrid queries through a single unified interface. Metadata filtering at query time uses MongoDB-style operators including $eq, $ne, $gt, $lt, $in, and logical combinators $and and $or, enabling precise result scoping without post-processing. The multimodal pipeline powered by OpenCLIP embeds text and images into a shared vector space, allowing cross-modal retrieval where text queries return relevant images and vice versa. Deployment options range from embedded mode via PersistentClient for notebooks and prototypes, to client-server mode with Docker for production, to Chroma Cloud for serverless scalability. Official Python and JavaScript SDKs provide identical APIs, and embedding function integrations support OpenAI, Cohere, Hugging Face, Google, Ollama, and custom models. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
MindsDB
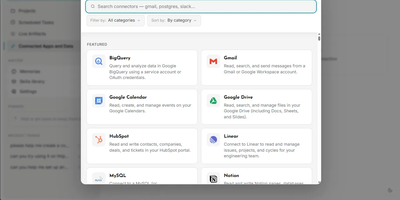
Backed by 39,500+ GitHub stars and over 339 releases, MindsDB delivers the open-source federated query engine that gives AI agents a single SQL interface to read, join, and aggregate across 200+ live data sources without any ETL pipelines or data movement. The Connect-Unify-Respond architecture wires up Postgres, MySQL, MongoDB, Snowflake, BigQuery, ClickHouse, Redshift, Databricks, Salesforce, Shopify, Slack, S3, GCS, Azure Blob, and dozens more through self-contained Python handler packages merged in the open from the community. Knowledge Bases fuse structured tables with vectorized unstructured data from PDFs, emails, support tickets, and documents using hybrid search combining vector similarity with keyword matching for retrieval-augmented generation. Jobs execute queries on configurable schedules refreshing Knowledge Bases nightly or syncing derived tables hourly, while Triggers fire on data changes to automatically vectorize new rows into the appropriate store. The SQL-compatible query language extends standard SQL with constructs for creating models, defining agents, managing workflows, and searching unstructured data. The built-in web editor at port 47334 provides interactive SQL authoring, while the MySQL-compatible API at port 47335 and PostgreSQL API at port 47336 connect any database client directly. An MCP Server integration exposes MindsDB to AI assistants, and the Python SDK enables programmatic access from application code. Docker deployment runs with a single command exposing all APIs immediately. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
ChartDB
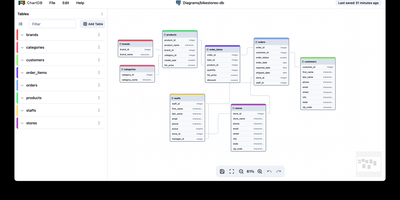
Paste one SQL query result into a browser and get an interactive entity-relationship diagram instantly, with no installations, no credentials, and no account required. ChartDB's "Smart Query" runs a single statement in your existing database client that exports table definitions, relationships, indexes, and column types as JSON metadata, meaning the application never touches your database passwords. The canvas renders draggable entities with cardinality markers, collapsible grouping areas, and sticky notes for documentation. AI-powered DDL export generates migration scripts between dialect pairs like PostgreSQL to MySQL or SQLite to CockroachDB, analyzing your schema to produce target-specific DDL with correct type mappings and constraint translations. Import paths cover Smart Query JSON, raw DDL scripts, and DBML files from tools like dbdiagram.io. The AI layer connects to OpenAI or any compatible inference server including local vLLM instances running models like Qwen2.5-32B. Database coverage includes PostgreSQL (with Supabase and Timescale extensions), MySQL, SQL Server, MariaDB, SQLite (with Cloudflare D1), CockroachDB, ClickHouse, and Oracle. Exports to SVG with inline styles or SQL DDL in any target dialect. Ships as a React/Vite frontend behind Nginx in Docker, deployable on RepoCloud with dedicated VPS resources under the AGPL-3.0 license.
QuestDB
Powering trading floors at firms processing millions of market data events per second and trusted by organizations including Airbus, Yahoo, and Copenhagen Atomics, QuestDB has earned over 17,000 GitHub stars as the time-series database that refuses to make you choose between ingestion speed and query latency. The column-oriented, time-partitioned storage engine processes millions of rows per second on ingest through write-ahead logging with instant durability, while SIMD-accelerated parallel execution returns analytical queries over billions of rows in milliseconds. Time-series SQL extensions add ASOF JOIN for point-in-time lookups across tables with misaligned timestamps, SAMPLE BY for downsampling at arbitrary time intervals, LATEST ON for last-value queries, and WINDOW JOIN for sliding window aggregations — all through standard SQL syntax accessible via the PostgreSQL wire protocol, REST API, or the QuestDB Wire Protocol (QWP) that streams Apache Arrow at 220 million rows per second. Multi-tier storage automatically moves data from the WAL through native columnar format to Parquet files on S3-compatible object storage, keeping hot data fast and cold data portable without manual tiering. The built-in web console provides an interactive SQL editor with syntax highlighting, autocomplete, and charting for quick data exploration. Views, materialized views, and n-dimensional arrays support real-time analytics, while native Parquet export enables direct integration with Python, DuckDB, and AI/ML frameworks. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
phpMyAdmin
Since 1998, phpMyAdmin has been the standard web interface for MySQL and MariaDB - the tool millions of developers, DBAs, and hosting companies reach for when a database needs inspecting, fixing, or migrating. Written in PHP, it covers effectively the entire administration surface: create, browse, alter, and drop databases, tables, views, columns, and indexes; insert and edit rows through a tabular editor; manage user accounts and granular privileges; and maintain stored procedures, triggers, and events - all without touching a command line. The SQL editor executes arbitrary queries with syntax highlighting, autocompletion, history, and bookmarkable statements, including batch queries. Import/export is a migration workhorse: read SQL, CSV, XML, and OpenDocument spreadsheets in; write out to SQL dumps, CSV, JSON, XML, PDF, Word, LaTeX, and more - the fastest path for moving a WordPress database or handing a schema to a colleague. The Designer view renders your schema as an interactive ER diagram with drag-and-drop relationship editing, and data transformations display BLOBs as images or download links inline. Server maintenance views surface configuration suggestions. Multi-server support, dark mode, and translations into 72 languages round out a tool that earns its ubiquity. GPL-licensed.
SurrealDB
With 32,800 GitHub stars, 180 contributors, and version 3.2 shipping in July 2026, SurrealDB eliminates the database zoo by unifying document, graph, relational, time-series, geospatial, and key-value data models into a single Rust binary queried through SurrealQL — an intuitive SQL-like language that handles graph traversals, record links, subqueries, and computed fields without switching between multiple database engines. Purpose-built for AI applications, it integrates vector indexing, full-text search, and hybrid retrieval that blends semantic similarity with graph and relational intelligence for context-aware RAG pipelines and recommendation engines. Real-time subscriptions and event-driven triggers push live data changes to connected clients without requiring external message brokers like Kafka. Multi-row, multi-table ACID transactions guarantee consistency while incrementally computed views deliver pre-calculated analytics without batch processing. Role-based access control with record-level permissions, JWT authentication, and multi-tenant isolation enables backend-as-a-service usage where client applications connect directly with fine-grained security. SDKs for JavaScript, Python, Go, Rust, .NET, and Java connect via WebSocket or HTTP APIs. Storage and compute separation allows deployment as an embedded library, a single-node server, or a highly-scalable distributed cluster with TiKV or FoundationDB backends. Deploy via Docker with persistent volumes on any Linux host. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Source-available licensed.
Budibase
Step right up to the magical world of Budibase, the open-source wizardry that turns the grueling task of building internal tools into a walk in the digital park. Imagine crafting mighty tools and formidable forms in less time than it takes to brew a cup of coffee, all without typing a single line of code! With Budibase, you can charm data from an ancient external database, summon information from a Rest API, conjure up figures from a CSV, or create something entirely new with Budibase's own mystical database. Design your digital dominion with a flick of the drag-and-drop, and automate your kingdom's workflows as if by magic. Join the ranks of the 75,000 teams who've harnessed the power of Budibase to accelerate their business quests. Need to safeguard data like a digital fortress, automate tasks like a sorcerer, or streamline operations like a high-speed chariot? Budibase is your trusty steed in the race to operational victory. And with RepoCloud hosting, you'll save a treasure chest of gold compared to those other cloud-dwelling giants!
Databasement
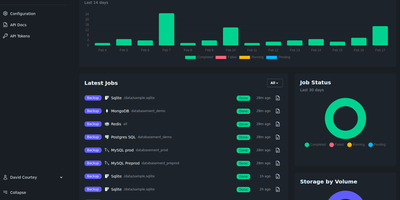
Databasement puts scheduled backup and restore for nine database engines behind one polished web interface, deployed as a single Docker container on port 2226. The Laravel and Livewire backend uses native CLI tools for MySQL 5.6 through 9.x, PostgreSQL 12 through 18, MariaDB 10.x through 12.x, Microsoft SQL Server 2017 through Azure SQL, MongoDB 4.2 through 8.0, SQLite 3.x, Firebird 3.x through 5.x, Redis 2.8+, and Valkey 7.2+ with full restore support including cross-server recovery. SSH tunnel connectivity reaches databases behind firewalls via bastion servers with password or private key authentication, and remote agents handle isolated networks by connecting outbound over HTTPS without inbound ports. Scheduling supports arbitrary cron expressions with GFS grandfather-father-son retention alongside simple time-based cleanup. Storage spans local disk, S3-compatible services including AWS and MinIO, Azure Blob, Samba/SMB shares, and SFTP/FTP servers. Scheduled restores automate production-to-staging synchronization on recurring intervals. Failure notifications alert via Email, Slack, Discord, Telegram, Pushover, Gotify, and webhooks with detailed job logs. The REST API and built-in MCP server enable CI/CD pipeline integration and AI assistant access from Claude, Cursor, and VS Code Copilot. 1,700+ stars since November 2025. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Cognee
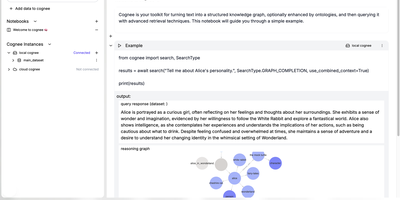
Cognee gives AI agents persistent long-term memory that survives across sessions, replacing the traditional stack of separate graph, vector, and session databases with a unified engine running on a single PostgreSQL instance. The memory-native API exposes four verbs (remember, recall, forget, and improve) enabling agents to persist context, retrieve cited answers, prune outdated knowledge, and self-improve from feedback. Under the hood, Cognee combines pgvector embeddings with a PostgreSQL-native graph store and cognitive-science-grounded ontology generation, delivering hybrid retrieval that fuses semantic similarity, structural graph traversal, and lexical search in a single query. Integrations span Claude Code, Cursor, LangGraph, OpenAI Agents, and any MCP-compatible client through a dedicated MCP server on port 8001, while the Python and TypeScript SDKs provide direct programmatic access. The platform supports swappable backends including Neo4j, FalkorDB, Qdrant, ChromaDB, Weaviate, Milvus, and LanceDB for teams with existing infrastructure. Built-in OpenTelemetry tracing, an experimental dashboard with knowledge graph visualization, multi-tenant user isolation, and audit trails ensure production readiness. Deploy via Docker Compose with optional profiles for PostgreSQL, Neo4j, Redis, and the web frontend. Reached v1.0 in April 2026 with 30,000+ stars. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.