OpenPencil
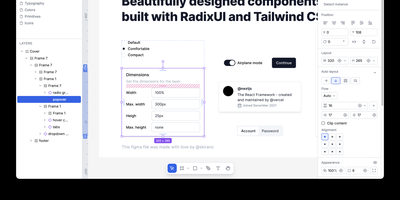
OpenPencil is the open-source design editor that reads and writes native Figma .fig files using the same Kiwi binary format — enabling bidirectional copy-paste between Figma and OpenPencil without data loss. The built-in AI assistant provides 90+ design tools through a chat interface, creating and modifying shapes, fills, strokes, auto-layout, components, variables, and boolean operations from natural language prompts, with BYOK support for Anthropic, OpenAI, Google AI, OpenRouter, Z.ai, MiniMax, and compatible endpoints. A Skia CanvasKit WASM renderer paired with Yoga WASM layout engine delivers Figma-parity rendering with flex and CSS Grid support including gap, padding, and alignment. The headless CLI inspects node trees via XPath queries, lints naming and accessibility, converts between document formats, analyzes color and typography patterns, extracts design tokens, and exports to PNG, SVG, JSX/Tailwind, and HTML. An MCP server exposes all design operations over stdio and HTTP, connecting Claude Code, Cursor, Windsurf, and Gemini CLI for AI-assisted design automation. Real-time P2P collaboration via WebRTC with Yjs CRDT synchronization requires no server and no account. The Vue SDK provides headless components for embedding the editor into custom applications. Ships as a 7 MB Tauri v2 desktop app for macOS, Windows, and Linux, or runs in any browser as a PWA. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
MongoDB
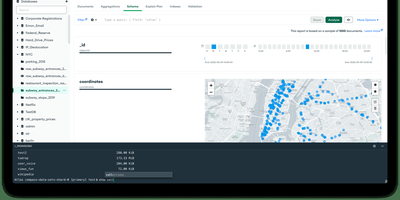
Used by over 46,800 companies including Forbes, Toyota, and Cisco, MongoDB stores data as flexible JSON-like BSON documents that eliminate rigid table schemas and support rapid application iteration. Its aggregation pipeline processes complex data transformations through composable stages including $match, $group, $lookup for joins, $unwind, and $project, operating directly within the database engine. Horizontal scaling is built in through automatic sharding, which distributes data across nodes using range-based, hashed, or zone-based shard keys, while replica sets provide automatic failover with configurable read preferences and write concerns. Multi-document ACID transactions span multiple collections and shards since version 4.0, enabling relational-style consistency guarantees within a document model. Starting with Community Edition 8.2, native full-text search and vector search are available directly in the database through $search and $vectorSearch aggregation stages, supporting RAG patterns, semantic retrieval, and hybrid search without external dependencies. Change streams provide real-time event-driven data access by tailing the oplog through the aggregation framework, enabling reactive architectures without polling. Time series collections offer optimized columnar storage for IoT sensor data and metrics with automatic bucketing and compression. Official drivers exist for Python, Node.js, Java, Go, C#, C++, Rust, Swift, and PHP, with MongoDB Compass providing a GUI for visual schema exploration and query building. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. SSPL v1 licensed.
Kite
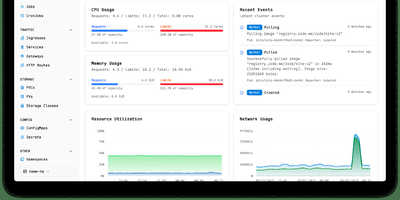
With nearly 3,000 GitHub stars and 14 releases since its June 2025 launch, Kite delivers a lightweight Kubernetes dashboard that replaces the fragmented workflow of switching between kubectl, Lens, and separate monitoring tools with a unified multi-cluster management platform. The dashboard automatically discovers clusters from kubeconfig files and supports independent Prometheus configurations per cluster, providing real-time CPU, memory, and network charts alongside live pod log streaming with filtering and search. A built-in web terminal opens shells directly into pods and nodes without kubectl port-forward, while the Monaco-based YAML editor offers syntax highlighting and validation for in-place resource editing. The integrated AI agent, powered by OpenAI or Anthropic models via native Go SDK integrations, translates natural language into precise client-go API calls — querying cluster health, analyzing pod logs, scaling deployments, patching resources, and cleaning up failed jobs — all operating strictly within the logged-in user's RBAC permissions. Enterprise governance includes OAuth 2.0 single sign-on, multi-factor authentication, FIDO2 passkeys, granular role-based access control with per-namespace permissions, and comprehensive audit logging. Helm chart management enables browsing, installing, and upgrading releases directly from the UI, while the Docker registry integration provides quick image tag selection. Deploy via a single Docker container with SQLite or use the official OCI Helm chart with PostgreSQL or MySQL for production. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Tiledesk
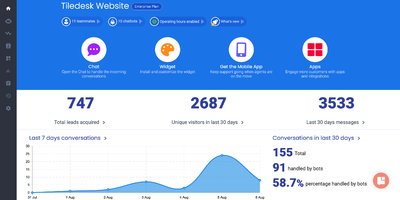
Tiledesk lets you build AI-powered conversational agents with a visual drag-and-drop designer, then deploy them simultaneously across web chat, WhatsApp, Telegram, Facebook Messenger, Instagram, email, and Slack without rebuilding per channel. The no-code Design Studio combines LLM-powered conversations with conditional logic, external API calls, and branching dialogue trees that work identically everywhere. Multi-RAG knowledge management separates content into isolated repositories with hybrid search combining traditional full-text retrieval and semantic understanding via Qdrant vector embeddings, enabling accurate answers even when users phrase queries in unexpected ways. LLM integration supports GPT-4, GPT-4o, Anthropic Claude, and any model exposing an OpenAI-compatible API including locally hosted models via Ollama for complete data sovereignty. The human-in-the-loop system provides seamless escalation from AI agents to live support staff with full conversation context preserved, while multi-agent workflows enable complex orchestration where specialized bots collaborate on different aspects of a customer interaction. REST and MQTT APIs power integration with external systems and webhook-triggered automations, and pre-designed templates accelerate common scenarios. Docker Compose deployment starts the full stack including server, dashboard, messaging engine, and widget. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Agent Gateway
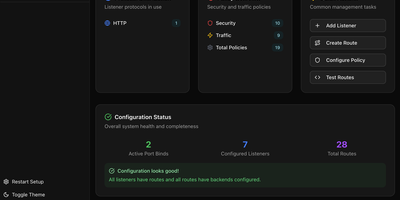
Backed by the Linux Foundation with contributions from AWS, Cisco, IBM, Microsoft, Red Hat, and Shell, Agentgateway is the first data plane built from the ground up for AI agent workloads — providing a unified Rust-based proxy that handles conventional HTTP and gRPC traffic alongside MCP tool servers, A2A agent communication, and LLM inference endpoints through a single deployment. The LLM gateway routes requests to OpenAI, Anthropic, Gemini, AWS Bedrock, and other providers through an OpenAI-compatible unified API with per-tenant budget controls, spend tracking, prompt enrichment, load balancing across multiple model endpoints, and automatic failover when providers experience outages. The MCP gateway federates multiple tool servers behind one endpoint, supporting stdio, HTTP/SSE, and Streamable HTTP transports with built-in OAuth authentication compliant with the MCP auth specification, integrating Auth0 and Keycloak out of the box. OpenAPI integration exposes existing REST APIs as MCP-native tools without code changes, enabling legacy services to participate in agent workflows. Policy-based RBAC controls which agents access which tools, while OpenTelemetry integration provides distributed tracing across agent communication chains. Deploy as a standalone binary with flat YAML configuration or on Kubernetes using the built-in controller with Gateway API support for declarative infrastructure-as-code management. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Karakeep
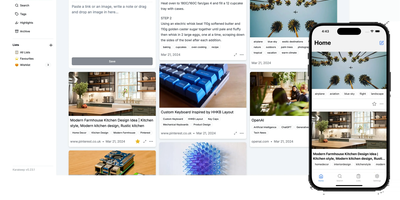
Previously known as Hoarder and now holding 28,000+ GitHub stars, Karakeep is the most popular open-source bookmark-everything application — combining AI-powered automatic tagging with full-text search, page archival, and cross-platform access for digital content hoarders who refuse to let valuable links disappear. The Next.js frontend with tRPC communication delivers a responsive interface for saving links, notes, images, and PDFs, while Puppeteer crawls bookmarked pages to fetch titles, descriptions, and images automatically. LLM-based auto-tagging supports OpenAI, Anthropic, or local models via Ollama for privacy-first deployments that never send data to external services. Meilisearch powers full-text and semantic search across all stored content including OCR-extracted text from images. A rule-based automation engine triggers custom actions based on bookmark properties — automatically sorting, tagging, or archiving content matching defined conditions. Full page archival via Monolith preserves complete page snapshots against link rot, while yt-dlp integration archives videos from YouTube and other platforms. RSS feed ingestion automatically captures new articles from subscribed sources. Collaborative lists enable teams to build shared bookmark collections, with per-list permissions and real-time sync. Native iOS and Android apps, Chrome and Firefox extensions, and browser bookmark sync via Floccus ensure capture from any device. Importers migrate data from Chrome, Pocket, Linkwarden, Omnivore, and Tab Session Manager. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Typing Mind
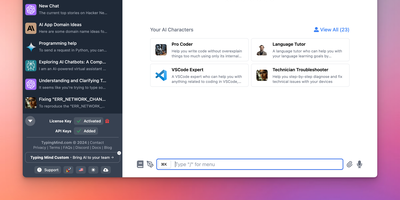
Bring your own API keys and work with OpenAI GPT models, Anthropic Claude, Google Gemini, Mistral, DeepSeek, Grok, Azure endpoints, and local models in one organized workspace: TypingMind is a unified chat frontend for large language models, replacing a browser tab per provider. Parallel chat sends the same prompt to multiple models and compares answers side by side, and models can be switched mid-conversation. A prompt library stores reusable, tagged prompts with variables, and the AI Agents system builds specialized assistants that bundle a base model, custom instructions, assigned plugins, and uploaded knowledge files for RAG. Plugins extend every connected model with web search, image generation (DALL-E, Stable Diffusion), Deep Research, URL reading via Firecrawl, and Zapier automation - plus MCP server integrations for Notion, Atlassian, and other external tools, and a JavaScript extension API for custom behavior. Chats store locally by default with optional sync. Self-hosting puts the interface on your own domain and, for teams, adds branding, member access limits, and shared prompt and agent libraries.
Macro
Macro merges email, team chat, collaborative documents, task management, CRM, and video calls into one keyboard-driven application where AI agents operate across the entire workspace with shared team memory, replacing the Slack plus Notion plus Linear plus Superhuman plus HubSpot stack with a single deployment. The email module provides a multi-account unified inbox with keyboard shortcuts, shared team inboxes, and Gmail integration. Team messaging offers channels and direct messages designed for technical discussions with threaded conversations. The task system draws from Linear with board and list views tightly integrated with channels, email threads, and AI agents. Real-time collaborative documents use CRDT synchronization via Loro for conflict-free editing with Markdown-native formatting and @mention linking. A 2D canvas board embeds @links to tasks, files, and emails for visual project planning. AI agents access unified team-level memory spanning all workspace modules, taking autonomous actions across email, chat, tasks, and documents through MCP-compatible tool interfaces. Video calls include recording, transcription, and automatic logging to team memory. The CRM module tracks customers and contacts with custom properties, email synchronization, and data enrichment. Eighty-plus Rust microservices on the Axum framework handle backend operations while a SolidJS static SPA delivers the frontend with instant search and real-time collaboration. Docker Compose deployment provisions the complete service stack with PostgreSQL, Redis, OpenSearch, and FusionAuth authentication. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Marimo
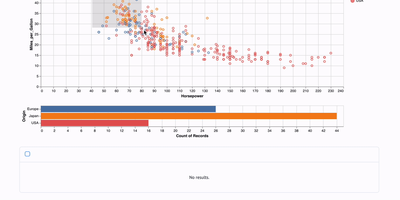
Marimo is a reactive Python notebook that treats cells like spreadsheet formulas: change one cell or interact with a UI widget and every dependent cell automatically re-executes, eliminating the hidden state bugs that make traditional notebooks unreliable. Backed by over 22,000 GitHub stars, notebooks are stored as pure Python files with PEP 723 inline metadata, making them Git-diffable, importable as modules, executable as CLI scripts with parameterized arguments, and testable with PyTest. Built-in SQL cells query Polars, Pandas, PyArrow, DuckDB, SQLite, PostgreSQL, and MySQL databases, with results automatically flowing into the reactive dependency graph. The AI-native editor provides GitHub Copilot autocomplete, context-aware assistants that access live runtime variables, inline code edits powered by configurable models from OpenAI, Anthropic, or local Ollama instances, and a pair mode that lets external AI agents connect over WebSocket. Notebooks become read-only interactive web applications with marimo run, collaborative authoring environments with marimo edit, or embedded flows inside existing FastAPI applications through ASGI middleware. Gallery mode serves multiple notebooks from a single instance with an auto-generated index page. The Docker image ships with SQL support, token-based authentication, health check endpoints at /health and /api/status, and configurable WebSocket or SSE kernel transport for proxy compatibility. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
GPT Researcher
A question goes in; a cited, long-form report comes out - GPT Researcher is an open-source autonomous research agent. A planner agent decomposes the query into sub-questions, execution agents crawl 20+ web sources in parallel with JavaScript-enabled scraping, and a publisher aggregates findings into a 2,000+ word report with inline citations, exportable to PDF, Word, and Markdown. The Deep Research mode extends this recursively: each result yields follow-up questions that are explored to configurable breadth and depth in a tree pattern, while accumulated learnings, citations, and visited URLs are shared across branches. It also researches local documents (PDF, CSV, Word) alongside the web. LLM and search providers are pluggable, including OpenAI, Anthropic, Google, DeepSeek, and Ollama for models, and Tavily, Google, Bing, DuckDuckGo, and SearXNG for retrieval. It ships as a Python package, a FastAPI server with web frontend, a Docker image, and an MCP server for use inside Claude or Cursor. MIT-licensed.
MindsDB
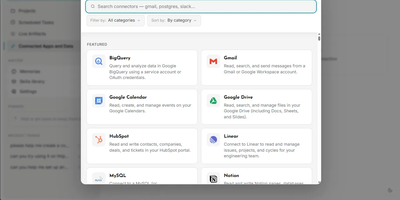
Backed by 39,500+ GitHub stars and over 339 releases, MindsDB delivers the open-source federated query engine that gives AI agents a single SQL interface to read, join, and aggregate across 200+ live data sources without any ETL pipelines or data movement. The Connect-Unify-Respond architecture wires up Postgres, MySQL, MongoDB, Snowflake, BigQuery, ClickHouse, Redshift, Databricks, Salesforce, Shopify, Slack, S3, GCS, Azure Blob, and dozens more through self-contained Python handler packages merged in the open from the community. Knowledge Bases fuse structured tables with vectorized unstructured data from PDFs, emails, support tickets, and documents using hybrid search combining vector similarity with keyword matching for retrieval-augmented generation. Jobs execute queries on configurable schedules refreshing Knowledge Bases nightly or syncing derived tables hourly, while Triggers fire on data changes to automatically vectorize new rows into the appropriate store. The SQL-compatible query language extends standard SQL with constructs for creating models, defining agents, managing workflows, and searching unstructured data. The built-in web editor at port 47334 provides interactive SQL authoring, while the MySQL-compatible API at port 47335 and PostgreSQL API at port 47336 connect any database client directly. An MCP Server integration exposes MindsDB to AI assistants, and the Python SDK enables programmatic access from application code. Docker deployment runs with a single command exposing all APIs immediately. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
MindsHub
Backed by $50M+ from Benchmark, Y Combinator, and NVIDIA with 800+ contributors and 39,000+ GitHub stars, MindsHub Cowork is the unified AI workspace where open-source models handle entire projects — research, reporting, internal tools, scheduled operations — and return finished, shareable deliverables. The platform runs two interchangeable open-source agent harnesses, Anton and Hermes, swappable from a dropdown without losing context. A built-in Model Router pre-wires 25+ models spanning Anthropic Claude, OpenAI GPT, Google Gemini, DeepSeek, Qwen, Kimi, Grok, and MindsHub Air with automatic failover — no per-provider API keys required. A secure credentials vault connects BigQuery, PostgreSQL, Salesforce, HubSpot, Zendesk, Gong, Gmail, Google Drive, Notion, Linear, Stripe, and Slack, keeping secrets scoped per connection so agents never see raw keys. Agent output becomes publishable artifacts — documents, dashboards, apps, and code — each deployable to a live shareable URL. Cross-session persistent memory, a reusable skill library, and a background scheduler supporting hourly, daily, and weekly cadences enable autonomous recurring workflows. The architecture separates a React/Vite frontend (shipping as both Electron desktop app and web SPA) from a FastAPI backend with a versioned REST API at /api/v1 covering conversations, projects, artifacts, schedules, and connectors. Self-host via Docker Compose with nginx on port 3000 and the API on port 26866, or deploy on-prem, in a VPC, or air-gapped. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Glean
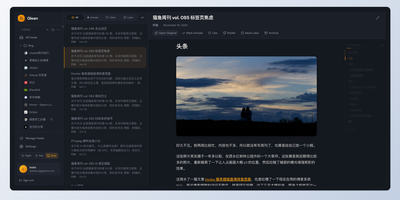
Information overload is the default state of the modern internet, and Glean exists to tame it by pulling every blog, newsletter, and news source you follow into a single, organized reading experience with an interface that prioritizes clarity over clutter. Subscribe to RSS and Atom feeds, import your existing subscriptions via OPML, and organize everything into multi-level folders with a flexible tagging system that lets you slice your reading list by topic, priority, or mood. A three-pane layout presents your feed list, article summaries, and full content side by side, with one-click actions for marking articles as read, saving them for later, bookmarking favorites, or archiving what you have already processed. Background workers fetch new articles every 15 minutes so your feeds stay current without manual refreshes. The preference learning engine (backed by Milvus vector embeddings) scores incoming articles against your reading history and surfaces a personalized Smart Feed of content you are most likely to care about, reducing the time spent scrolling past irrelevant posts. A built-in MCP server lets AI assistants like Claude Desktop search and interact with your feed library directly. The admin dashboard on a separate port provides user management, system monitoring, and configuration controls for multi-user deployments. Bookmark external URLs from any browser with the Chrome extension, or access your feeds on mobile through the Progressive Web App. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Sage Wiki
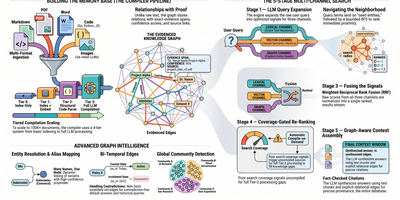
Sage Wiki turns a pile of unstructured documents into a fully interlinked, searchable wiki by running them through a five-pass LLM compiler pipeline. Inspired by Andrej Karpathy's vision of LLM-compiled knowledge bases, the pipeline processes source files through diff detection, summarization, concept extraction, image captioning, and cross-reference discovery, with parallel LLM calls and checkpoint/resume for vaults scaling to 100,000+ documents. The typed ontology graph stores entities and relations with BFS traversal, configurable relation types, multilingual synonyms, and a promotion/demotion lifecycle backed by grounding verification and consensus scoring. Multi-format ingestion handles Markdown, PDF, Word, Excel, PowerPoint, EPUB, email, CSV, images, and code files without manual tagging. LLM provider support spans Anthropic, OpenAI, Gemini, Ollama, and any OpenAI-compatible API, with per-pass model routing enabling cost optimization by assigning cheaper models to simpler tasks. The built-in MCP server exposes 17 tools over SSE transport for integration with Claude, Cursor, and any MCP-compatible agent, while native Obsidian vault overlay ensures existing note workflows remain undisrupted. Team deployment supports Git-synced shared wikis, centralized server access, and hub federation across multiple projects. Ships as a single Go binary with Docker Compose multi-arch images serving the web UI on port 3333. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Airbyte
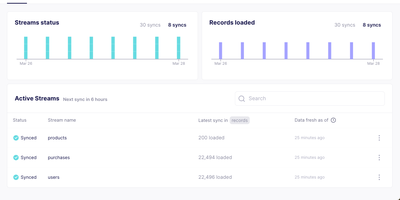
Backed by over 21,800 GitHub stars and more than 1,000 community contributors, Airbyte has become the standard open-source data movement platform, powering ELT pipelines for organizations ranging from startups to Fortune 500 enterprises. The platform provides 600+ pre-built connectors covering PostgreSQL, MySQL, MongoDB, Snowflake, BigQuery, Redshift, S3, Salesforce, HubSpot, Stripe, Shopify, Google Analytics, and hundreds of additional APIs, databases, and SaaS applications. The no-code Connector Builder lets practitioners create new source connectors in minutes by pointing at an API documentation URL, while the Python CDK enables custom connectors with full programmatic control for complex authentication flows and pagination strategies. Airbyte's AI agent capabilities include the MCP Gateway for Model Context Protocol integration, the open-source Agent SDK compatible with pydantic-ai, LangChain, OpenAI Agents, and FastMCP, and a Context Store that lets AI agents query business data across connected systems without runtime API stitching. Change Data Capture streams incremental updates from PostgreSQL, MySQL, and SQL Server using Debezium, while dbt integration handles post-load transformations within the pipeline. Self-hosted deployment uses Kubernetes via the abctl CLI tool, which bootstraps a local kind cluster with a single command, or Helm charts for production clusters with Keycloak OIDC authentication and secrets management through AWS Secrets Manager, Google Secrets Manager, or HashiCorp Vault. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. ELv2 licensed with MIT-licensed connectors.
PostHog
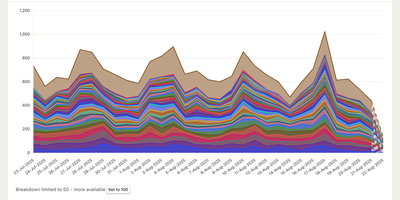
With over 37,000 GitHub stars and used by teams at Y Combinator, Airbus, and Phantom, PostHog replaces an entire stack of paid analytics tools — Mixpanel, Amplitude, Heap, LaunchDarkly, Hotjar, and Google Analytics — with a single open-source platform where every tool shares a common event layer and user context. Product analytics captures events automatically or via manual instrumentation with HogQL (SQL) access for custom queries, while web analytics provides GA-like dashboards for traffic, conversions, and Core Web Vitals. Session replay records user interactions with DOM snapshots and network waterfall analysis, linking directly to errors and feature flag exposures. Feature flags safely roll out changes to specific cohorts with multivariate support and instant rollback, while experiments run A/B tests with automatic Bayesian significance calculations and revenue attribution. Error tracking captures stack traces linked to session replays and user properties for immediate reproduction context. AI observability monitors LLM generations, traces, token usage, latency, and costs across model versions. The managed data warehouse syncs 120+ external sources including Stripe, Postgres, Salesforce, and HubSpot alongside product events, queryable through a unified SQL editor. An MCP server enables AI agents in Cursor, Claude Code, or VS Code to query analytics and execute SQL directly. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
MetaMCP
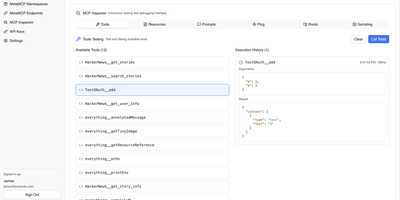
With 2,600+ GitHub stars, MetaMCP solves the MCP server sprawl problem by aggregating any number of upstream servers into a single authenticated endpoint that any MCP client connects to once. Group servers into namespaces — development tools in one, data sources in another — then publish each namespace as its own SSE, Streamable HTTP, or OpenAPI endpoint with API-key authentication in headers or query parameters, or full OAuth per the MCP Spec 2025-06-18 standard. The aggregation engine discovers tools, resources, and prompts from all active servers in parallel, prefixes tool names with server identifiers to prevent collisions, and applies configurable middleware including tool filtering to reduce context-window bloat and description overrides to improve LLM comprehension. The web management UI lets you configure MCP servers with stdio, SSE, or Streamable HTTP transports, toggle servers active or inactive per namespace, create and revoke API keys per endpoint, and inspect discovered tools with their schemas. Nested MetaMCP support enables hierarchical architectures where one MetaMCP instance consumes another, creating multi-level tool organization with automatic name resolution. Compatible with Claude Desktop, Claude Code, Cursor, Open WebUI, and any MCP-compatible client through a single connection URL. The Docker container packages the TypeScript backend with PostgreSQL for configuration persistence, exposing the management UI on port 12005 and MCP endpoints on configurable ports. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Utopia
The first open-source substrate for enterprise knowledge engineering that learns passively and governs itself. The Rust-built backend paired with PostgreSQL and pgvector delivers a bitemporal knowledge graph where every fact carries two timelines: when it held in the real world and when the system came to believe it — enabling full audit trail replay of how understanding evolved. Document ingestion handles PDF, DOCX, PPTX, XLSX, CSV, Markdown, HTML, and plain text with legacy encoding detection, while scheduled syncing pulls from web pages, RSS feeds, GitHub, Jira, Notion, WebDAV, and S3-compatible buckets. Search fuses Tantivy full-text indexing with pgvector semantic vectors using Reciprocal Rank Fusion, streaming answers with inline citations that link directly to source passages. The built-in agent harness drives agentic RAG through conversation — searching documents, walking the knowledge graph at any historical date, and querying mounted databases via Ontology2SQL which achieves state-of-the-art results on BIRD Mini-Dev benchmarks. Five ontology packs ship inside the binary (schema.org, W3C Org, PROV-O, FOAF, IOF Core) with forward-chaining reasoning for transitivity, symmetry, inverses, and relation hierarchy. Entity resolution operates in three stages: exact name matching, embedding similarity, then model-based judgment with every merge reversible. Any OpenAI-compatible endpoint works including DeepSeek, Qwen, Ollama, and vLLM for fully air-gapped deployment. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.