Nocobase
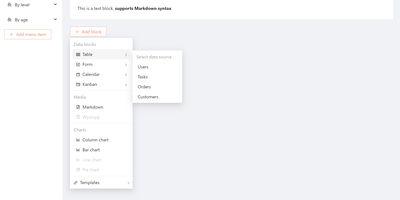
CRMs, project trackers, inventory tools - NocoBase is an open-source no-code/low-code platform for building business systems like these. Its architecture is data-model driven: you define collections and relationships first, then compose any number of interface blocks (tables, forms, kanban, charts) on top of the same model, so data structure is never coupled to a particular view. The core is a microkernel where every feature is a plugin, WordPress-style; you enable official plugins, install marketplace ones, or write your own as npm packages with server and client parts. Data sources include the main PostgreSQL or MySQL database, external databases, and third-party APIs - so you can build admin panels over existing production data instead of migrating it. Built-in infrastructure covers role-based permissions down to collection, record, and field level, workflow automation with approval steps and scheduled triggers, and audit logs; a one-click switch flips between usage and configuration modes. Because custom features live in isolated plugins with a documented lifecycle, core upgrades do not overwrite your customizations, and swapping UIs never requires data migrations since interfaces sit on independent models. Written in TypeScript on Node.js, Koa, and React under the AGPL license, it is light enough for one person to run and extend - and where no-code SaaS platforms charge per seat and per app, a self-hosted instance runs unlimited applications for unlimited users at hosting cost alone.
Supabase
With over 107,000 GitHub stars and adoption by teams at Mozilla, 1Password, Peerlist, and thousands of startups, Supabase has become the most widely deployed open-source Firebase alternative — built entirely on PostgreSQL rather than a proprietary NoSQL store. Every project provisions a dedicated Postgres database with 40+ preinstalled extensions, auto-generating REST APIs via PostgREST, GraphQL via pg_graphql, and real-time change streams via an Elixir-based WebSocket engine that supports database change listeners, user presence tracking, and arbitrary broadcast messaging. Authentication covers email and password, phone OTP, magic links, and 20+ social providers including Google, GitHub, Apple, Azure, and SAML SSO, all enforced through Postgres Row Level Security policies that run inside the database itself. S3-compatible object storage delivers files through a CDN spanning 285+ cities with on-the-fly image transformations powered by imgproxy. Edge Functions run globally distributed TypeScript on the Deno runtime with Node.js compatibility and access to over two million NPM packages. The pgvector extension stores, indexes, and queries vector embeddings for AI-powered semantic search and retrieval-augmented generation workflows. Supabase Studio provides a browser-based dashboard with a table editor, SQL editor, schema visualizer, and log explorer. Official client SDKs ship for JavaScript, Python, Flutter, Swift, Kotlin, C#, Go, and Ruby. The self-hosted Docker Compose stack runs fourteen coordinated services including Kong API gateway, Supavisor connection pooler, and Logflare analytics. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Baserow
Airtable's spreadsheet-database model, self-hostable and open-source: that is Baserow. It presents data in a spreadsheet-style grid, but underneath each table is a real relational structure with typed fields, links between tables, filters, sorts, and multiple views (grid, gallery, form, kanban, calendar). Beyond the database core, it includes an application builder for composing pages and portals on your data, workflow automations, and dashboards. Everything is API-first: each table exposes a REST endpoint with token auth and webhooks, so it plugs directly into n8n, Zapier, or custom scripts. The stack is Django (Python) on the backend, Vue.js on the frontend, PostgreSQL for storage, with Redis for async tasks. Core features are MIT-licensed; premium features are a paid add-on. The self-hosted version has no row, storage, or API request limits - Airtable's per-base record caps and monthly API quotas simply don't exist here, and capacity is bounded only by your PostgreSQL database and disk. Existing Airtable bases, CSVs, and Excel files import directly with structure preserved, so migration doesn't start from a blank slate, and both the backend and frontend support plugins for custom field types and integrations without forking the core. For non-technical teammates the interface behaves like a spreadsheet; for engineers, the data model is the API.
Teable
An Airtable-style spreadsheet interface directly on PostgreSQL: Teable is an open-source no-code database where every table is a real Postgres table. Unlike tools that store records in a metadata abstraction layer, every Teable table is a real Postgres table with standard column types, so filtering, sorting, and grouping run at database speed, million-row tables answer complex filters in roughly 200 milliseconds without index tuning, and any PostgreSQL-compatible tool - psql, BI dashboards, ETL pipelines - can query the same data directly. The interface offers Grid, Kanban, Gallery, Calendar, and Form views as non-destructive overlays with their own filters and hidden fields, plus 20+ field types, formulas, comments, attachments, batch editing, undo/redo, and edit history. Collaboration is real-time with live cursors and instant sync across views, backed by Redis, and a REST API is auto-generated per table, largely compatible with Airtable API clients - alongside native SQL access for BI tools, analytics pipelines, and your own applications to JOIN and query directly, with no exports, API rate limits, or sync jobs. Global search spans all records, chart plugins handle quick visualization, and CSV and Excel import/export cover migrations. Where Airtable caps paid plans at 100K-500K rows and charges roughly $20 per user per month, a self-hosted Teable instance has neither limit: the Postgres database itself is the export if you ever leave. Built in TypeScript with NestJS, deployed via Docker with PostgreSQL and Redis, and licensed AGPL-3.0.
FalkorDB
FalkorDB is the first queryable property graph database to leverage sparse adjacency matrices and linear algebra for graph traversal, replacing traditional pointer-chasing with GraphBLAS-accelerated computation. Originally the RedisGraph engine, it was relaunched as FalkorDB in 2023 and rewritten from C to Rust in 2026 for improved memory safety and performance. The database supports the OpenCypher query language with proprietary extensions, translating queries into linear algebra expressions that exploit AVX hardware acceleration. Indexing options include full-text search, vector similarity for embedding-based retrieval, and range indexing, while connectivity supports both the RESP protocol for Redis clients and the Bolt protocol for Neo4j-compatible tooling. The GraphRAG SDK enables ingestion of documents in text, PDF, and Markdown formats into knowledge graphs, with schema-guided entity extraction, hybrid retrieval combining vector and graph traversal, relationship expansion, and cited answers for LLM applications. Official client libraries cover Python, Node.js, Java, Rust, Go, PHP, and C#. Multi-tenant support handles over 10,000 concurrent graphs with zero overhead and full isolation. Docker deployment runs the falkordb/falkordb image on ports 6379 for the database server and 3000 for the built-in browser UI, with persistent volume storage and optional authentication. A production falkordb-server image excludes the browser for lighter deployments. On RepoCloud, deploy FalkorDB on a dedicated VPS with root SSH access, persistent storage for your graph data, and complete control over authentication, thread count, and memory configuration, all under the SSPLv1 license.
QuestDB
Powering trading floors at firms processing millions of market data events per second and trusted by organizations including Airbus, Yahoo, and Copenhagen Atomics, QuestDB has earned over 17,000 GitHub stars as the time-series database that refuses to make you choose between ingestion speed and query latency. The column-oriented, time-partitioned storage engine processes millions of rows per second on ingest through write-ahead logging with instant durability, while SIMD-accelerated parallel execution returns analytical queries over billions of rows in milliseconds. Time-series SQL extensions add ASOF JOIN for point-in-time lookups across tables with misaligned timestamps, SAMPLE BY for downsampling at arbitrary time intervals, LATEST ON for last-value queries, and WINDOW JOIN for sliding window aggregations — all through standard SQL syntax accessible via the PostgreSQL wire protocol, REST API, or the QuestDB Wire Protocol (QWP) that streams Apache Arrow at 220 million rows per second. Multi-tier storage automatically moves data from the WAL through native columnar format to Parquet files on S3-compatible object storage, keeping hot data fast and cold data portable without manual tiering. The built-in web console provides an interactive SQL editor with syntax highlighting, autocomplete, and charting for quick data exploration. Views, materialized views, and n-dimensional arrays support real-time analytics, while native Parquet export enables direct integration with Python, DuckDB, and AI/ML frameworks. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
Nhost
Backed by 9,200 GitHub stars and venture funding led by Nauta Capital, Nhost is the open-source Firebase alternative that replaces Google's proprietary document store with a relational PostgreSQL foundation from day one. The Hasura integration auto-generates a real-time GraphQL API with subscriptions, role-based permissions, and remote schemas from your PostgreSQL tables, while event triggers and cron triggers automate backend workflows without custom infrastructure. Authentication supports email and password, magic links, phone OTP via SMS, social OAuth providers including Google and GitHub, WebAuthn for passwordless login with Face ID, fingerprints, and YubiKeys, plus two-factor authentication. Since the Q1 2026 release, Nhost Auth also functions as a full OAuth2 and OpenID Connect provider, allowing your Nhost project to issue tokens to third-party applications the same way GitHub or Google do. The S3-compatible storage service handles file uploads with automatic image optimization, virus scanning, and presigned URLs for secure direct downloads. Node.js serverless functions deploy JavaScript and TypeScript backend logic without managing servers, while the Nhost CLI spins up the complete local stack via Docker for development with automatic database migration tracking and Hasura metadata management. The MCP server integration exposes project documentation and data schemas to AI assistants for intelligent query building. SDKs cover JavaScript, TypeScript, React, Vue, Next.js, and Dart for Flutter. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. MIT licensed.
Chroma
With over 29,000 GitHub stars and deep integrations into LangChain, LlamaIndex, and CrewAI, Chroma has become the default vector database for developers building retrieval-augmented generation pipelines and AI agent memory systems. Its core API consists of just four functions — create, add, query, and delete — making it the fastest path from zero to semantic search, while the underlying Rust engine handles tokenization, embedding, HNSW indexing, and similarity scoring automatically. Chroma supports dense vector search via HNSW with configurable distance metrics including L2, cosine similarity, and inner product, sparse vector search using SPLADE, full-text BM25 keyword search, and regex matching, all combinable in hybrid queries through a single unified interface. Metadata filtering at query time uses MongoDB-style operators including $eq, $ne, $gt, $lt, $in, and logical combinators $and and $or, enabling precise result scoping without post-processing. The multimodal pipeline powered by OpenCLIP embeds text and images into a shared vector space, allowing cross-modal retrieval where text queries return relevant images and vice versa. Deployment options range from embedded mode via PersistentClient for notebooks and prototypes, to client-server mode with Docker for production, to Chroma Cloud for serverless scalability. Official Python and JavaScript SDKs provide identical APIs, and embedding function integrations support OpenAI, Cohere, Hugging Face, Google, Ollama, and custom models. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
PocketBase
An entire backend in a single Go executable: PocketBase embeds SQLite with realtime subscriptions, authentication and user management, file storage, and an admin dashboard, all behind a REST-ish API. SQLite runs in WAL mode, which outperforms client-server databases for the read-heavy workloads typical of small and mid-sized apps. Authentication supports email/password, one-time passwords, and 15+ OAuth2 providers including Google, Apple, and GitHub, with stateless tokens. Clients subscribe to record changes over server-sent events, and official JavaScript and Dart SDKs cover web, mobile, and Flutter frontends. Collections, rules, and API access permissions are managed visually in the admin UI. When you need custom logic, extend it with JavaScript hooks running in the embedded JS VM of the prebuilt binary, or import PocketBase as a Go library and compile custom business logic into your own single-file backend. File storage attaches uploads to records with thumbnail generation for images and optional S3-compatible external storage. All state lives in one pb_data directory, so backup is a directory copy and upgrade is replacing a binary - one of the lowest-maintenance backends you can run. The contrast with Firebase is the point: where usage-based pricing scales with reads, writes, and bandwidth, PocketBase runs the entire backend at flat hosting cost, and the data is a plain SQLite file you can copy anywhere. MIT-licensed.
Redis
Processing billions of operations per second across companies like Twitter, GitHub, Snapchat, and Stack Overflow, Redis is the world's fastest and most widely deployed in-memory data store. Redis 8 unifies previously separate modules into a single distribution: RediSearch for full-text indexing with BM25 scoring and vector similarity search via HNSW and FLAT algorithms, RedisJSON for native JSON document storage with JSONPath queries, RedisTimeSeries for timestamped data with configurable downsampling compaction rules, and RedisBloom for probabilistic data structures including Bloom filters, cuckoo filters, count-min sketches, top-k, and t-digest. The core engine provides strings, lists, sets, sorted sets, hashes, streams, HyperLogLog, bitmaps, bitfields, geospatial indexes, and the new array data structure introduced in Redis 8.8. Pub/Sub delivers lightweight real-time messaging between publishers and subscribers, while Streams provide an append-only log with consumer groups for event sourcing and complex consumption patterns. Redis Cluster distributes data across nodes with automatic sharding using 16,384 hash slots, and Sentinel provides high availability with automatic failover monitoring. Lua scripting and Redis Functions enable server-side computation, and ACL-based security provides granular per-command, per-key access control. Official clients exist for Python, Node.js, Java, Go, .NET, Rust, and PHP. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPLv3 licensed.
Budibase
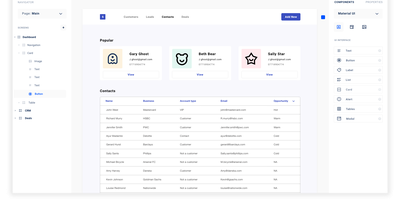
Step right up to the magical world of Budibase, the open-source wizardry that turns the grueling task of building internal tools into a walk in the digital park. Imagine crafting mighty tools and formidable forms in less time than it takes to brew a cup of coffee, all without typing a single line of code! With Budibase, you can charm data from an ancient external database, summon information from a Rest API, conjure up figures from a CSV, or create something entirely new with Budibase's own mystical database. Design your digital dominion with a flick of the drag-and-drop, and automate your kingdom's workflows as if by magic. Join the ranks of the 75,000 teams who've harnessed the power of Budibase to accelerate their business quests. Need to safeguard data like a digital fortress, automate tasks like a sorcerer, or streamline operations like a high-speed chariot? Budibase is your trusty steed in the race to operational victory. And with RepoCloud hosting, you'll save a treasure chest of gold compared to those other cloud-dwelling giants!
OpenViking
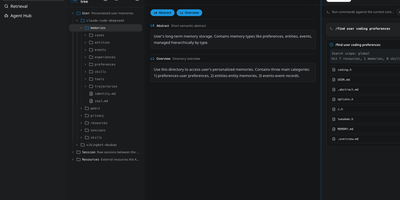
OpenViking is a self-hosted context database that gives AI agents persistent, structured memory by organizing knowledge, skills, and session history into a hierarchical virtual filesystem accessible through the viking:// URI protocol. Instead of dumping everything into a flat vector store and hoping semantic search finds the right chunks, agents navigate their context with familiar commands like ls, tree, and find, locating exactly the information they need through deterministic paths combined with semantic search. Every resource is automatically processed into three layers: a 100-token L0 abstract for quick filtering, a 2,000-token L1 overview for content navigation, and the full L2 detail loaded only when confirmed necessary. This tiered approach cuts token consumption by 83 to 96 percent compared to conventional RAG while improving task completion rates by 15 to 49 percent on benchmark tests. The built-in memory self-iteration loop automatically analyzes task execution and user feedback, updating agent memory directories so the system continuously learns and improves. You can connect to any LLM provider, including Ollama for fully local inference, OpenAI, or compatible gateways. The Web Studio UI at the /studio endpoint provides visual browsing of the entire context filesystem, and the REST API on port 1933 supports programmatic access. Deploy via Docker, Kubernetes with the included Helm chart, or as a standalone service. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. AGPL-3.0 licensed.
Cognee
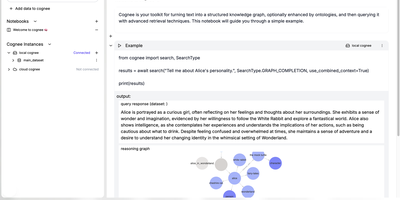
Cognee gives AI agents persistent long-term memory that survives across sessions, replacing the traditional stack of separate graph, vector, and session databases with a unified engine running on a single PostgreSQL instance. The memory-native API exposes four verbs (remember, recall, forget, and improve) enabling agents to persist context, retrieve cited answers, prune outdated knowledge, and self-improve from feedback. Under the hood, Cognee combines pgvector embeddings with a PostgreSQL-native graph store and cognitive-science-grounded ontology generation, delivering hybrid retrieval that fuses semantic similarity, structural graph traversal, and lexical search in a single query. Integrations span Claude Code, Cursor, LangGraph, OpenAI Agents, and any MCP-compatible client through a dedicated MCP server on port 8001, while the Python and TypeScript SDKs provide direct programmatic access. The platform supports swappable backends including Neo4j, FalkorDB, Qdrant, ChromaDB, Weaviate, Milvus, and LanceDB for teams with existing infrastructure. Built-in OpenTelemetry tracing, an experimental dashboard with knowledge graph visualization, multi-tenant user isolation, and audit trails ensure production readiness. Deploy via Docker Compose with optional profiles for PostgreSQL, Neo4j, Redis, and the web frontend. Reached v1.0 in April 2026 with 30,000+ stars. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.
dbx
Universal database administration across modern enterprise infrastructure is simplified through dbx, a lightweight web client and SQL studio supporting over ninety database engines. Database administrators connect to MySQL, PostgreSQL, SQLite, Redis, MongoDB, ClickHouse, DuckDB, Oracle, and Microsoft SQL Server through authenticated network connections and encrypted SSH tunnels. The interactive query editor provides real-time multi-schema autocomplete, syntax linting, execution plan analysis, and natural language SQL query synthesis powered by configurable large language model backends. Teams visualize complex relational database architectures using interactive entity-relationship diagrams that map table foreign key constraints, primary indexes, and table partition layouts automatically. Operators inspect live Redis memory usage breakdowns, monitor real-time server command throughput, and manage key expirations without opening raw terminal sessions. The editable data grid supports multi-row modifications, foreign key reference lookups, CSV and JSON exports, and binary blob data inspection directly inside the browser viewport. Software developers expose connected databases directly to external AI coding assistants through native Model Context Protocol server endpoints. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
Valkey
With 26,600 GitHub stars, 50 contributing companies including AWS, Google Cloud, Oracle, and Ericsson, and governance under the Linux Foundation ensuring the BSD 3-Clause license can never be revoked by a single entity, Valkey delivers a truly open-source Redis-compatible key-value datastore that reached 1.19 million requests per second in version 8.0 through redesigned asynchronous I/O threading across CPU cores while maintaining single-threaded data structure operations for predictability. Native data structures include strings, hashes, lists, sets, sorted sets, bitmaps, HyperLogLogs, streams, and geo-spatial indices with JSON support through modules. Valkey 9.0 shipped full-text search and aggregation via Valkey Search, enabling tag queries, numeric filtering, and text matching directly within the datastore without external search engines. Cluster mode provides horizontal scaling with automatic sharding, replication for high availability, and per-slot metrics for granular monitoring. Lua scripting enables complex atomic operations, while the module plugin system extends the server with custom commands and data types including probabilistic Bloom filters. Client libraries for Python, Java, Go, Node.js, and PHP maintain full Redis OSS protocol compatibility — existing Redis applications work without code changes. Deploy as a standalone daemon or in clustered mode with Docker, supporting persistent and ephemeral workloads on any Linux host. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. BSD 3-Clause licensed.
Appwrite
Backed by over 56,000 GitHub stars and a growing ecosystem of client and server SDKs covering Flutter, React Native, Swift, Kotlin, Python, Node.js, Deno, and more, Appwrite provides a complete backend platform that replaces Firebase and Supabase with a fully self-hostable architecture. The authentication module supports email and password, phone OTP, magic links, OAuth providers including Google, GitHub, Apple, and Facebook, anonymous sessions, and JWT token management with configurable session policies. The database service provides a document-oriented store with collections, indexes, query filters, pagination, and real-time subscriptions that push changes to connected clients instantly via WebSocket. The storage service handles file uploads with built-in image manipulation including cropping, resizing, format conversion, and compression, served through a CDN-ready URL structure. Serverless functions execute custom backend logic triggered by HTTP requests, scheduled cron jobs, or database events, with runtime support for Node.js, Python, PHP, Ruby, Dart, Swift, Kotlin, and Java. The messaging service enables push notifications, SMS, and email delivery through configurable providers including APNS, FCM, Twilio, Vonage, Mailgun, and Sendgrid. Team management with role-based permissions, webhook integrations, and health monitoring APIs complete the platform. The admin console provides a web-based dashboard for managing all services, monitoring usage metrics, and configuring project settings. Deployment runs via Docker Compose with MariaDB for metadata and configurable storage adapters. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. BSD 3-Clause licensed.
InsForge
With 12,600 GitHub stars and 52 releases in under a year of development, InsForge is the fastest-growing open-source backend platform purpose-built for AI coding agents — giving Claude, Cursor, and any MCP-compatible tool direct access to database, authentication, storage, compute, and AI model infrastructure through a single self-hosted stack. The native MCP server exposes every InsForge operation as callable tools, letting coding agents autonomously create database tables, manage user authentication, upload files, deploy edge functions, and ship complete full-stack applications without human intervention. The Model Gateway provides an OpenAI-compatible API that routes requests across multiple LLM providers (OpenAI, Anthropic, Google, and open-source models) with unified billing, rate limiting, and fallback logic. PostgreSQL with pgvector handles both relational data and vector embeddings for RAG pipelines, while S3-compatible storage manages file uploads and static assets. Edge Functions run serverless TypeScript code on Deno with sub-millisecond cold starts for API endpoints, webhooks, and scheduled tasks. The authentication system provides user management, OAuth2 flows, sessions, and magic links with JWT token handling built in. Site Deployment builds and serves frontend applications with automatic SSL and custom domain configuration. The CLI paired with Agent Skills enables terminal-based workflows where agents invoke InsForge operations directly from the command line. Deploy via Docker with PostgreSQL as the only required external dependency. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache-2.0 licensed.
OpenSearch
OpenSearch is a search and analytics platforms, powering full-text search, log analytics, observability, and AI-powered vector retrieval at petabyte scale. The distributed engine provides BM25 full-text search alongside k-NN vector search using NMSLIB, Faiss, and Lucene libraries, enabling semantic search, hybrid search combining keyword and vector scoring through normalization processors, neural sparse search, and retrieval-augmented generation workflows with built-in ML Commons for model hosting. OpenSearch Dashboards delivers interactive visualization with Discover for log exploration, custom dashboards, alerting, anomaly detection using Random Cut Forest algorithms, and Security Analytics with detection rules mapped to MITRE ATT&CK. Native Prometheus integration with full PromQL support unifies metrics alongside logs and traces in a single observability interface, while Data Prepper handles telemetry ingestion from OpenTelemetry collectors, Fluent Bit, and Logstash-compatible pipelines. SQL and Piped Processing Language queries with a visual PPL builder enable analysts to query data without learning the native DSL. Index State Management automates index lifecycle with rollover, shrink, and delete policies, while cross-cluster replication and searchable snapshots on S3-compatible storage provide disaster recovery. Scoped API keys, field-level security, document-level security, and audit logging deliver enterprise-grade access control. Docker Compose deploys multi-node clusters alongside the Kubernetes operator for orchestrated production environments. Running on a dedicated VPS on RepoCloud with guaranteed CPU, RAM, and SSD, full root SSH access, and a browser serial console. Apache 2.0 licensed.